Blog innovation
October 24, 2026
Meet the Three Teams Turning African Challenges into AI Research at TRI AI Cohort 10 Demo Day
Meet the Three Teams Turning African Challenges into AI Research at TRI AI Cohort 10 Demo Day
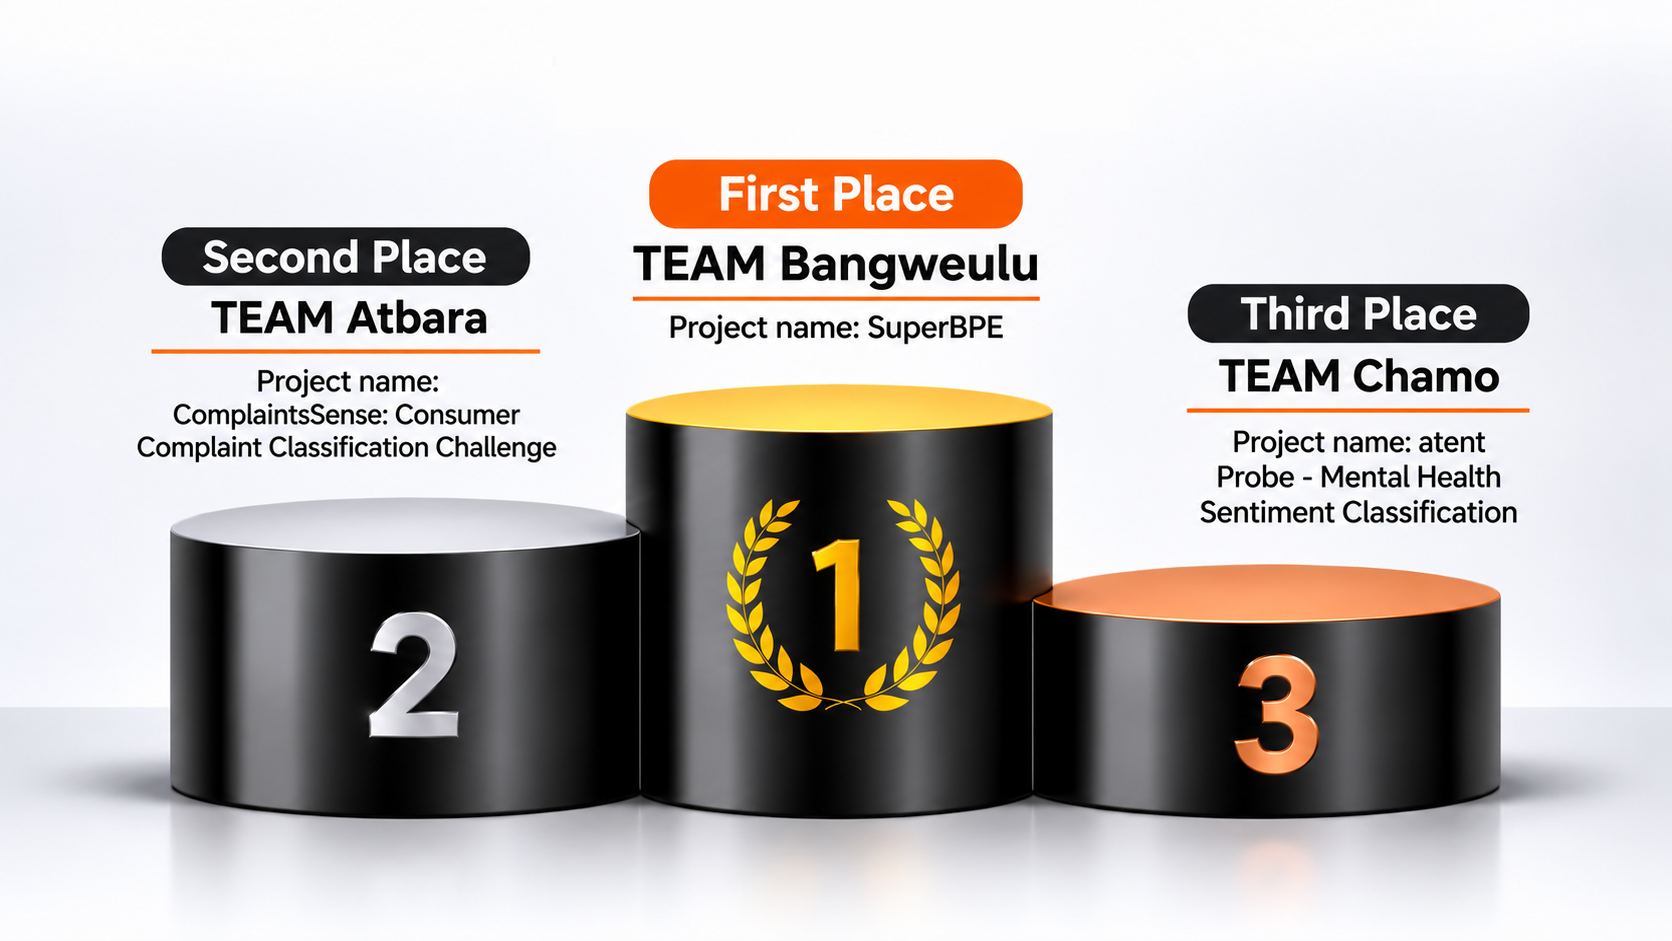
Tokenisers for African languages, a financial complaint classifier that understands Pidgin and Sheng, and a lightweight model for spotting mental health distress: meet the three teams that won TRI AI’s Cohort 10 Demo Day.
On Saturday, 3 October 2026, nine finalists presented the projects they built on the AI Research Foundation Course 1-4 at TRI AI’s Cohort 10 Demo Day.
Three teams won: Team Bangweulu took first place, Team Atbara second and Team Chamo third.
We spoke to each team lead about their project, what went wrong along the way, what the course gave them and what comes next.
At a glance
- Team Bangweulu (1st): a tokeniser designed for African languages
- Team Atbara (2nd): financial complaint analysis that understands local language
- Team Chamo (3rd): lightweight AI for spotting signs of mental health distress in text
Team Bangweulu: Rethinking How AI Processes African Languages
Team lead: Wiam Atfi
Core development team: Wiam Atfi and George Aladejana
Early contributors: Adejare Emmanuel and Olakunle Adeyemi Obasoro
Mentor: Elinah Moyo
Project: Explore the project on GitHub
Before an AI model reads a sentence, a tokeniser chops the text into small pieces, called tokens, that the model can work with. Most tokenisers were built around English and other well-resourced languages, and they can handle African languages poorly.
Many African languages are morphologically rich: a single word can carry several meaningful parts, much like a whole English phrase packed into one word. A tokeniser that doesn’t recognise those parts may shatter the word into many fragments. According to Team Bangweulu, that means more tokens, higher computing costs, slower processing and, potentially, a weaker representation of meaning.
The team built a morphologically aware SuperBPE tokeniser, a variant of the standard byte-pair encoding method, aimed at making tokenisation more efficient across more than 30 African languages.
For the team, this is about more than saving tokens. African languages shouldn’t be disadvantaged because the tools that process them were never designed with them in mind.
The challenge behind the model
The hardest part was the data. Some languages have far more text available than others, so a tokeniser trained on everything would be dominated by the best-represented languages.
To correct for this, the team grouped languages by linguistic type, sampled from them in shuffled order and capped each group at the size of the smallest dataset. That kept any one language from claiming a disproportionate share of the vocabulary.
The course gave the team a firm grounding in tokenisation and embeddings. Wiam also singled out data cards and impact statements, which pushed the team to think about how technical performance relates to real-world impact.
What winning meant
For Wiam, the win brought joy and pride after weeks of late nights and technical pivots.
“Winning validated every late night, every technical pivot, and our team’s shared dedication to building meaningful infrastructure for African languages.”
Tokenisation benchmarks are only the start. The team’s next step is to plug the tokeniser into an active large language model pipeline and measure the effect on text generation, training efficiency and reasoning. That will show whether better tokenisation produces real gains in practice.
Wiam’s advice to other builders: stay resilient, and test your assumptions hard. In research, progress often starts with discovering that your first approach can be improved.
Team Atbara: Making Financial Complaint Analysis More Context-Aware
Team lead: Justina Odoeze
Team members: Nzube Ohalete, Sheree Edmund, Faith Kasunga and Sheila Nalweyiso
Project: Explore the project on GitHub
As digital payments and cross-border commerce grow, banks and payment providers receive huge volumes of customer complaints. Making sense of them isn’t easy, especially when customers write in local expressions, informal language or a mix of languages.
Team Atbara noticed that customer-service tools built around standard English or rigid keyword rules often stumble on Nigerian Pidgin, Kenyan Sheng and other everyday forms of speech. Complaints can also refer to payment systems and financial services specific to one country.
The cost of getting it wrong is real: complaints sent to the wrong team, delayed fixes and urgent problems that go unnoticed. The team set out to build an AI approach that reads complaints in context.
Learning to define the problem carefully
The team’s motivation was personal. Several members had dealt with customer-service systems that misunderstood them or sent their complaint to the wrong place.
The biggest hurdle in development was agreeing on how to label complaints consistently. Take a complaint about food that arrived cold after a late delivery. Is that a product-quality problem or a delivery problem? If team members answer differently for similar examples, the training data becomes inconsistent.
The team consolidated its labelling rules, used AI to apply them more consistently and added an “unclear” category for ambiguous complaints, which it left out of training.
For Justina, the lesson was that model development begins long before training: the quality of the labels and the choices made in data preparation shape what a model learns. She credited the course’s modules on problem statements and data ethics with helping the team frame the problem and handle its data carefully.
A result that means more than a placement
Justina remembers screaming with joy when the team was announced as a winner, a reward for weekly meetings, tight deadlines and a lot of collaboration.
“This recognition strengthened my confidence that I belong in the research community and have something meaningful to contribute to shaping the future of AI in Africa.”
The team now plans to deepen its research and work towards publishing its findings.
Justina’s advice for other African AI learners: start with a specific problem that matters to your community, and understand it before you build anything. Pay attention to data quality and ethics, work with others, stretch beyond what you already know, and aim for projects that are useful beyond a notebook. In her words, understanding the problem properly matters as much as choosing the model.
Team Chamo: Exploring Lightweight AI for Mental Health Support
Team lead: Bruno Nwagbo
Team members: Daniel Ohachor, Bassey Emmanuel Francis and Ademola James Aderemi
Mentor: Odion Joel Okonofua
Project: Explore the project on GitHub
In many African communities, mental health care is hard to reach. There are too few professionals, distances are long and stigma stops people from asking for help.
Team Chamo is exploring whether AI can pick up potential signs of mental health distress in everyday text, such as messages and online conversations. People often express distress informally long before they speak to a healthcare professional. The team wanted a resource-efficient approach that could support early identification where computing power and professional care are both limited.
A text model cannot diagnose a mental health condition on its own. Any real-world use would need careful evaluation and clinical oversight.
Distinguishing distress from everyday emotions
The team’s main technical challenge was making sure the model didn’t treat ordinary negative emotions as clinical distress, while keeping it light enough to run cheaply. A sad, fearful or angry message doesn’t necessarily point to a mental health condition, and a model that confuses the two will mislead.
To teach the difference, the team added 30,000 “hard negative” statements to its dataset of 52,681 mental health statements. These were messages expressing sadness, fear or anger that were labelled as non-distress.
Bruno said the course’s modules on representation learning, regularisation and rigorous evaluation shaped how the team probed the model and tuned its hyperparameters.
From a research project to responsible application
Bruno felt happy, humbled and proud when the team was announced as a winner. He hadn’t expected a top-three finish, which made it mean more after weeks of experimentation and dataset curation.
His next steps are about using the work responsibly as much as turning it into a product. The team wants to improve how the model handles Nigerian linguistic nuance, including Pidgin and local languages, and to work with mental health practitioners to check its accuracy.
Bruno is also wary of misuse. He wants the project developed ethically and used for good, never for stereotyping or profiling people, a risk that matters for any tool that interprets people’s emotional states.
His advice to African AI builders: focus on genuine community problems, and don’t let limited computing resources put you off. Careful problem framing and data engineering, he argues, can matter more than raw computing power or fine-tuning ever-larger models. Put ethics and real-world usability first from the start, stay consistent, and trust your team and mentors.
Watch the Complete recording session of the Demo Here - Link
What’s next
Congratulations to Team Bangweulu, Team Atbara and Team Chamo.
Want to follow in their footsteps? Applications for TRI AI Saturdays Cohort 11, run with Google DeepMind, will be announced through our newsletter, The Encoder (see newsletter form below).